
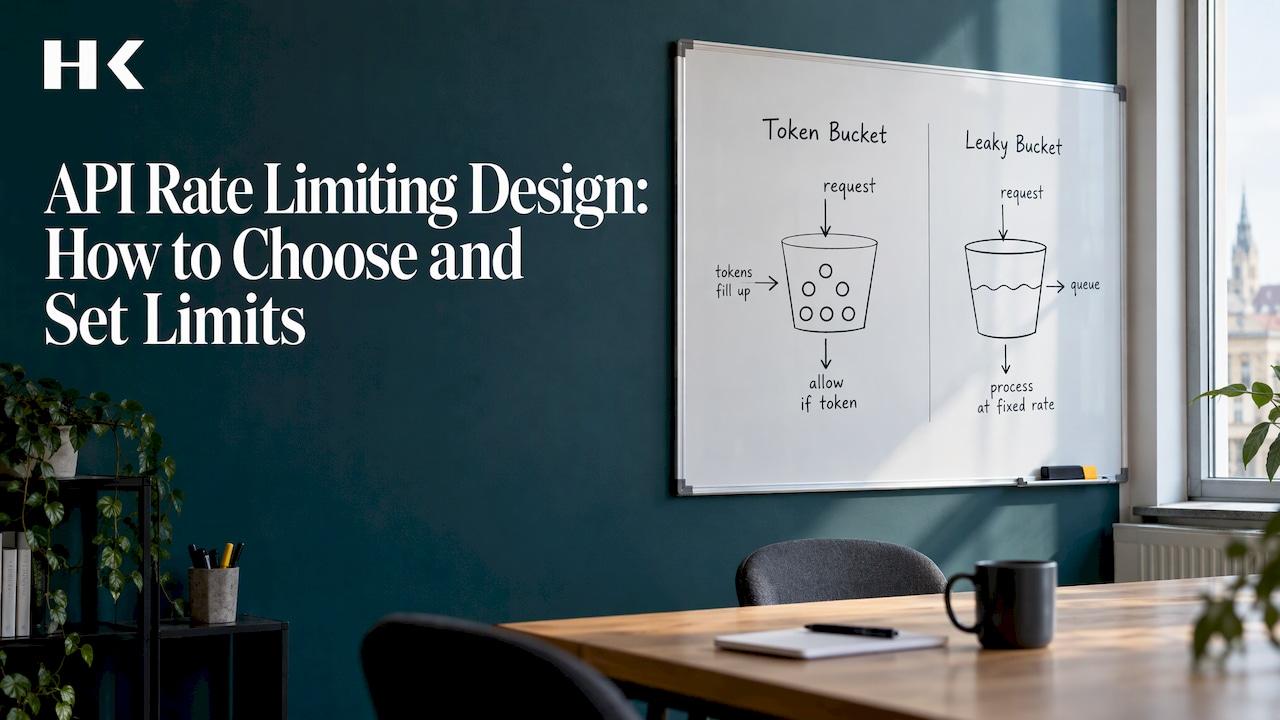
Rate limiting means your API refuses to serve a client that sends too many requests in a given time. To design it well, decide three things: who is counted (a user, a tenant, an API key), what is counted (requests, tokens, or in-flight jobs), and what happens at the limit. For most public or customer-facing APIs the answer is a token bucket per customer, a clear HTTP 429 response with a wait time, and a limit set from a load test rather than a guess.
I'm Hanad, a senior software engineer in Vienna. I rebuild prototypes made in tools like Lovable, Bolt and Bubble into maintainable code. Missing rate limits are one of the first gaps I find in them. This guide is written for founders and owners who aren't engineers but need to understand the decisions well enough to ask for the right thing.
Key Takeaways
- Rate limiting protects you from overload, abuse and runaway cost, and it gives you a fair way to sell plans with different usage.
- Use a token bucket per customer by default. It lets normal bursts through and still enforces an average rate.
- Define at least two kinds of limit: one per user or tenant, and one per endpoint to protect your infrastructure.
- Reject with HTTP 429 and a Retry-After header so well-behaved clients know how long to wait.
- Set numbers from a load test, write them down, and put the expensive endpoints (login, AI calls, exports) under tighter limits.
Table of Contents
- What rate limiting is and why a prototype needs it
- Decide what you are limiting
- Token bucket vs leaky bucket
- Other strategies you will hear about
- Set numbers from evidence, not guesses
- What the API should say when a limit is hit
- Mistakes I see in prototypes and inherited code
- My view: put limits in the first real version
- When to get help
- FAQ
- Sources
What rate limiting is and why a prototype needs it
A rate limit caps how many requests one caller can make in a window of time. Microsoft's documentation lists the reasons cloud APIs use it: preventing overload, fair usage, mitigating DDoS and other abuse, managing cost and keeping service quality.
For a founder, the practical reading is simpler:
- One customer shouldn't slow down everyone else. A single script in a loop can use the capacity your other customers are paying for.
- Your bill follows your traffic. If each request calls a paid service (an AI model, an SMS provider, a database that scales by usage), unlimited requests mean an unlimited invoice.
- Login and password-reset endpoints attract attackers. Without limits, anyone can try thousands of passwords.
Prototypes built in no-code or AI app builders usually have none of this. They work with five testers. They fall over, or run up a bill, when real users arrive. If your prototype stalled around launch, this is a likely cause. My broader guide to designing, setting and enforcing limits goes deeper into the engineering side.
Decide what you are limiting
Before picking an algorithm, answer three questions. Getting these wrong hurts more than choosing a slightly wrong algorithm.
Who is the caller?
The limit needs a key: the thing you count against. Common keys are the logged-in user, the customer account (tenant), the API key, or the IP address. Microsoft's Azure guidance recommends defining at least one user limit and one service limit for each API. User limits can use identifiers such as the workload identity, a subscription or a tenant. They keep one customer from crowding out another. Service limits, set per operation, protect your infrastructure from total demand.
For a B2B product, the tenant is usually the right key. If you only limit per user, a customer with 200 seats gets 200 times the allowance of a customer with one seat, which may or may not match your pricing.
IP addresses are a weak key on their own. Many legitimate users share one office address, and attackers rotate theirs. Research on rate-limit patterns also notes that identity-based limits can be evaded when people share credentials or create extra accounts. So combine keys: a per-account limit for normal use, plus a stricter per-IP limit on signup and login.
If you run on Cloudflare Workers, the platform's rate-limit binding accepts any string you choose as the key, so account ID or API key both work.
What is the unit?
Not every request costs the same. A request to fetch a user's name is cheap. A request that generates a PDF report or calls a language model is expensive. Counting them equally lets a client stay within the limit and still do damage.
AI APIs show the pattern clearly. OpenAI documents limits on requests per minute, tokens per minute and other measures, and whichever limit is hit first applies. A client can hit its request ceiling while far below its token ceiling, or the reverse. If your product wraps an AI model, you inherit these limits and need your own on top. I cover that case in a separate guide to OpenAI rate limits.
What happens at the limit?
You have three options: reject the request immediately, delay it in a queue, or degrade it (return cached or reduced data). Rejecting is simplest and right when a person is waiting. Queueing fits background work. The next sections cover both.
Token bucket vs leaky bucket
These two names appear in almost every guide, and they confuse people because they describe nearly the same idea.
Token bucket. Picture a bucket that holds, say, 100 tokens and refills at 10 tokens per second. Each request takes one token. If the bucket is empty, the request is rejected. A client that has been quiet has a full bucket and can send a burst of 100 at once, then settles to 10 per second. Apache APISIX describes it as a pool with limited capacity, refilled at a fixed rate, which allows short bursts while controlling the average rate. It also warns that setting the burst capacity too high can still overload your backend.
Leaky bucket. Picture a bucket with a hole. Requests pour in the top and drain out the bottom at a constant speed. If the bucket overflows, extra requests are dropped. Redis's guide puts the difference this way: a token bucket shapes the input and tolerates bursts, while a leaky bucket shapes the output at a constant pace, however bursty the input is.

There is a subtlety. Used purely as a counter (a "meter"), a leaky bucket behaves the same as a token bucket with equivalent settings. Wikipedia's explanation notes this equivalence, and says the real difference appears when a leaky bucket is used as a queue that releases requests at a fixed rate. That queue version adds waiting time instead of errors, up to the queue's size.
Which one should you pick?
| Situation | Pick | Why |
|---|---|---|
| Public or customer-facing API, a person or app is waiting | Token bucket | Real clients send bursts; excess fails fast and the client retries |
| Background jobs calling a fragile downstream system | Leaky bucket as a queue | Steady, predictable output; callers can wait |
| Login, password reset, one-time codes | Sliding window or strict token bucket with a small capacity | Boundary bursts must not slip through |
| AI inference, file uploads, long reports | Concurrency limit | The bottleneck is jobs in progress, not requests per minute |
The last two rows follow a widely cited guide's mapping of limiter types to API shapes. The rule of thumb in the first two rows comes from Redisson's explainer: if a human is waiting, reject fast with a token bucket and let the client retry; if the work is asynchronous and the downstream needs protecting, queue it.
Vercel's guidance adds a warning: leaky bucket is the most misapplied algorithm, because its failure mode is starvation, where old queued requests crowd out newer legitimate ones on a public endpoint. For a first version of a customer-facing API, start with a token bucket.
Other strategies you will hear about
Two more approaches come up often.
Fixed window. Count requests in each clock minute (for example 100 per minute) and reset at the boundary. It is simple and cheap, but it has a known flaw: a client can send 100 requests at 12:00:59 and another 100 at 12:01:00. Apache APISIX notes this boundary burst. That means up to twice the limit in a couple of seconds.
Sliding window. This smooths the boundary problem by looking at a rolling period. A common version, the sliding-window counter, combines weighted counts from the current and previous windows, so it avoids storing every request timestamp. A sliding-window log is exact but its memory use grows with traffic.
For internal endpoints and webhook receivers, a fixed window is usually fine. For anything an attacker would target, use a sliding window or a small token bucket.
You will also see concurrency limits, which cap how many requests are being processed at the same moment. They suit slow, heavy work such as AI calls, where ten simultaneous jobs can hurt more than a hundred small requests.
Set numbers from evidence, not guesses
The most common mistake I see is a limit picked because it sounds round. "100 per minute" means nothing until you know what your system can handle.
AWS's Well-Architected guidance gives a sound process: establish your service's capacity with load testing, document the tested limits, and don't raise a limit beyond what testing supports. It also suggests queues or streams where work can be done asynchronously.
A practical routine for a small product:
- Find the ceiling. Run a load test against a copy of your production setup and note where response times degrade or errors begin.
- Split the capacity. Set the total of all customer limits somewhat below that ceiling, so no single customer can use it all.
- Tier by endpoint. Give cheap reads generous limits. Give logins, signups, exports and AI calls tight ones.
- Tier by plan. If you sell Free, Pro and Enterprise plans, tie the allowance to the plan. This is where rate limiting becomes a pricing tool. If usage is part of what customers pay for, see my guide on usage-based billing for SaaS.
- Write the limits down. Put them in your API documentation so customers can plan around them.
- Review after launch. Look at who actually hits the limits. Raise a limit for a good reason, not because someone complained.
A worked example: say your load test shows the backend degrades at about 600 requests per second in total. You expect at most 20 active customers at once. A token bucket of 20 requests per second with a burst capacity of 40 per customer keeps the sum comfortably under the ceiling even if every customer bursts. Login gets its own rule, say 5 attempts per minute per account and per IP. These numbers are illustrative; yours come from your own test.
What the API should say when a limit is hit
A good rate-limited API tells the client what happened and what to do next.
- Return HTTP 429 (Too Many Requests) when a caller exceeds its own limit.
- Include a Retry-After header with the number of seconds to wait. AWS's guidance describes using HTTP 429 with Retry-After as an integer number of seconds for user-limit breaches.
- Use a 503 (Service Unavailable) when the problem is your service's overall capacity, not that caller's behavior. Add retry guidance only when retrying is safe.
The standard background: RFC 6585 recommends including Retry-After with 429 responses, and the header itself is defined in the HTTP standard.
This makes the rejection part of your resilience, not a failure. Throttling responses let consumers handle the error and retry later. Tell your own front end and your integration partners to wait and retry, not to hammer the endpoint again immediately. Retrying instantly makes an overload worse.
Mistakes I see in prototypes and inherited code
- No limit at all. The default in most app builders. It works until the first scraper, bug or viral day.
- Limits only in the browser. A button that disables itself is not a limit. Anyone can call your API directly. Enforce on the server.
- One global counter. A single limit for the whole API lets one heavy customer block everyone.
- Limits that reset on every deploy or on every server. If the counter lives in one server's memory and you run several servers, each one counts separately. Counters need shared storage or an edge service built for it.
- Identical limits for cheap and expensive endpoints. Your AI call and your health check should not share a budget.
- Silent failures. Returning a 500 error or an empty page at the limit leaves customers thinking your product is broken.
- No monitoring. If you can't see who is being limited, you can't tell abuse from a customer who has outgrown their plan.
Rate limiting is also one item in a wider security picture. My SaaS security checklist for B2B teams puts it alongside authentication, access control and logging. If you're deciding what an early API should include at all, API design for an MVP covers the decisions to make before you build.
My view: put limits in the first real version
Founders often treat rate limiting as something to add after launch. I think that's backwards, and the reason is cost, not purity. Retrofitting limits into code that nobody can read is slow and risky. Adding them while the first real version is built takes a small part of the project.
When I rebuild a prototype, the prototype is the specification: it shows me what users do. The rebuild is where I add the things a prototype skips, such as limits per account, tighter rules on login and payment endpoints, and clear 429 responses. I use a deliberately boring stack (TypeScript, Next.js, Node, Cloudflare Workers, SQL) so that the next developer can read it and change a limit without a rewrite.
The numbers are never mine alone to pick. You own the code from the first commit, and the limits are documented so you can raise them as your customers and plans grow.
Hanad Kubat
When to get help
If you're a non-technical founder, you do not need to write limiter code yourself. You need to know what to ask for: a limit per customer, stricter limits on login and expensive endpoints, a clear 429 with Retry-After, and a documented, tested ceiling.
I offer a fixed-price Prototype Audit for €1,500 (3 to 5 days, credited against the build) that shows what your current prototype is missing, rate limiting included. Builds start from €12,000, and rescue rebuilds run €12,000 to €20,000. The price is possible because there is no agency overhead, no project-manager layer and no offshore markup. You speak directly to the senior engineer who builds it. If your prototype is breaking under real users, have a look at what I build.
FAQ
What does API rate limiting mean?
It means capping how many requests a caller can make to your API within a set time, such as 100 per minute. Requests above the cap are rejected or delayed. The goal is to keep the service stable, fair across customers and affordable to run.
Is a token bucket or a leaky bucket better?
For a public or customer-facing API, a token bucket is the usual choice because it allows normal bursts and rejects excess quickly. A leaky bucket used as a queue suits background work that must reach a fragile system at a steady pace. Used as a simple counter, the two behave the same.
What should an API return when the limit is reached?
Return HTTP 429 with a Retry-After header giving the seconds to wait. Use 503 when the problem is the service's overall capacity rather than that caller's usage. Clients should wait and retry later, not repeat the request right away.
How do I fix a "rate limit reached" error as a user of someone else's API?
Wait for the time in the Retry-After header, then retry, ideally with increasing pauses between attempts. Reduce unneeded calls by caching results and batching requests. If you still hit the ceiling, ask the provider about a higher plan or limit. For AI providers, the OpenAI rate limits guide explains the specifics.
Where should the limit be enforced?
On the server or at the edge, never only in the browser. Counters must be shared across all servers running your API, or each server will count separately and the real limit will be higher than you set.
Sources
- What Is Rate Limiting? (Microsoft Learn)
- Design throttling to improve resilience (Microsoft Azure Well-Architected)
- API Rate Limit Adoption: A pattern collection (ACM)
- Rate Limiting, Cloudflare Workers docs
- Rate limits (OpenAI)
- API Gateway Rate Limiting: Algorithms (Apache APISIX)
- API throttling: Algorithms, patterns and mistakes to avoid (Redis)
- Leaky bucket (Wikipedia)
- Rate Limiting in ASP.NET Core (.NET 10)
- Rate Limiting Algorithms Explained (Redisson)
- Rate limiting strategies for APIs (Vercel)
- REL05-BP02 Throttle requests (AWS Well-Architected)
- HTTP 429 Too Many Requests: Causes, Headers and Retry Logic